

If I want better email forecasts, I need better data – not better guesses.
The article’s main point is simple: when I use campaign history, subscriber behavior, CRM records, and purchase data together, I can forecast opens, clicks, conversions, churn, bounce risk, and revenue with much more precision than with one average rate.
Here’s the short version:
- Past campaign data shows patterns over time, not just one-off results.
- CRM and purchase data connect email activity to sales and revenue.
- Send time, subject line, and segmentation sharpen pre-send estimates.
- Models like logistic regression, random forests, gradient boosting, and neural networks turn that data into probability scores.
- Open rate is easy to forecast, but it’s less reliable now because privacy tools can inflate opens.
- Clicks, conversions, churn, and bounce forecasts are more tied to business results.
- Clean data matters most: at least 10,000 subscribers, 6 months of history, and 1,000 conversions is a practical starting point.
- Post-send review matters: I need to compare predicted vs. actual results and fix repeated gaps.
A few numbers stand out:
- Segmented campaigns showed 14.31% higher open rates and 100.95% higher click rates in one large analysis.
- One segmented vs. non-segmented study found 42.5% vs. 28.7% opens, 18.3% vs. 9.5% CTR, and 7.8% vs. 3.4% conversions.
- One open-rate model reported R² = 77.53%, RMSE ≈ 5.16, and MAE ≈ 3.60.
- A January 2026 analysis said email drove the highest revenue while using 10.7% of total marketing spend.
My takeaway: if I want forecasts that help with budget, CAC, lead goals, and revenue planning, I should stop leaning on list-wide averages and start with clean, connected data.
That’s the core idea the article builds on.
Data Sources That Improve Forecast Accuracy
Historical Campaign Metrics and Subscriber Behavior
Time-stamped campaign history is the starting point for email forecasting. Open rates, click-through rates (CTR), conversion rates, bounce rates, and unsubscribe rates all matter. But they become far more useful when you track them over time at the subscriber level instead of treating them like one static snapshot. That gives models the signal they need to project future opens, clicks, conversions, and revenue.[7][11][1]
That long-view data matters for a simple reason: predictive models work best when they can see patterns, not one-off events. A subscriber who hasn’t engaged in 60 to 90 days carries a different churn risk than someone who skipped just one send. Steady drops in opens and clicks across several months are strong signs of future churn or non-engagement, while a weak result in a single campaign might just come down to bad timing or an offer that didn’t land.[7][10]
Historical engagement can account for more than 20% of model importance in some systems.[1] A 90–180 day lookback can also support RFM-style scoring for contacts that are active, fading, dormant, or at-risk.[6][4][1]
Email history helps predict engagement. CRM data pushes that forecast closer to revenue.
CRM and Transactional Data as a Stronger Forecast Base
Email metrics can tell you who opened or clicked. They can’t tell you who bought, how much they spent, or where they sit in the customer journey. That’s where CRM and transactional data come in.
Purchase history, average order value (AOV), repeat purchase behavior, and lifecycle stage help forecasting models predict revenue per campaign, customer lifetime value, and churn risk, not just opens.[4][7][11] When you combine that data with email engagement, the model can separate two very different people:
- A contact who clicks a lot but rarely converts
- A contact who clicks less often but reliably makes purchases
Bringing CRM, web, and email data together keeps the forecast tied to revenue instead of surface-level engagement.
Once that data base is in place, send time, subject line, and segmentation make the forecast sharper.
Key Predictors: Send Time, Subject Line, and Segmentation
Research keeps pointing to the same three factors: send time, subject lines, and segmentation.[7][8][9]
Send-time and subject-line history both strengthen pre-send forecasts. Send-time models use at least 90 days of per-subscriber open data to find when each person is most likely to engage.[12][13] Say a subscriber usually opens emails between 8:00–10:00 AM Eastern Time on weekdays. In that case, the model gives higher predicted open rates to sends in that window.[12][13]
Subject-line models also look at features such as length, personalization, urgency, and discount cues to predict opens and clicks before the email goes out.[7][11] One study that combined subject-line and sender features with historical data reported an R² of about 77.5%, which means those inputs explained a large share of the variation in open rates.[2][1]
Segmentation pushes forecast quality even further. A large Mailchimp analysis found that segmented campaigns produced 14.31% higher open rates and 100.95% higher click rates than non-segmented sends.[14][5] Why does that happen? Because list-level averages blur the differences between high-value repeat buyers, new leads, and inactive subscribers. They do not react to the same message in the same way.
Behavioral, value-based, and lifecycle segmentation each surface different response patterns, giving forecasting models the detail they need to project acquisition outcomes.[4][7][12]
These inputs feed the regression and machine-learning models covered next.
sbb-itb-2ec70df
Prediction Methods Used in Email Forecasting Research
From Regression to Machine Learning Models
Once the inputs are ready, the next job is picking a model that can turn that data into a forecast. In acquisition work, forecasts usually come from four main model groups: logistic regression, decision trees and random forests, gradient boosting models, and neural networks.[15][18][1]
Logistic regression is often the first baseline. It takes campaign and engagement features and returns a probability from 0 to 1 that a target event – like an open, click, or conversion – will happen.[15][18] One reason teams like it is simple: it’s easier to read than many other models. Analysts can look at the inputs and see which factors push the probability up or down.
Decision trees and random forests are useful when the pattern isn’t a straight line. They can deal with interactions, nonlinear relationships, and mixed data types without much manual feature engineering.[15][19] Gradient boosting models – including XGBoost, LightGBM, and CatBoost – work by building trees one after another, with each new tree trying to fix the last model’s mistakes. In click-through rate prediction studies, gradient boosting often gets near state-of-the-art results on structured marketing data.[2][15][19]
Neural networks tend to make more sense when a company has a lot of data and more complex inputs, such as subject-line text embeddings or multi-channel behavior histories.[15][1] One churn study found that a neural network beat logistic regression on the same dataset, though simpler models still worked better on smaller samples.[21]
How Probability-Based Forecasting Supports Acquisition Planning
These probability scores aren’t just academic output. They feed straight into send strategy, segmentation, and budget choices. The models estimate the likelihood of opens, clicks, conversions, churn, or bounces.[15][1][6]
That makes planning a lot more concrete. Subscribers with a high predicted conversion probability can be moved to higher-value offers or more personalized content. People with high churn risk can be sent into win-back flows before they drift away.[6][20]
Model Families Compared by Use Case
Model choice depends on the size of the dataset, the kind of features available, and the target you want to predict. Put simply, the right model changes based on whether the target is binary or numeric.
| Model Family | Typical Inputs | Forecast Target | Key Validation Metric | Practical Strength |
|---|---|---|---|---|
| Logistic Regression | Campaign metadata, segment flags, engagement history | Open probability, conversion probability, churn probability | AUC / F1 | Interpretable; good baseline for small-to-medium datasets |
| Decision Trees / Random Forests | Behavioral data, device type, send-time patterns, CRM attributes | Open probability, expected open rate, churn probability | RMSE / MAE | Handles mixed data types; stable parallel-tree baseline |
| Gradient Boosting (XGBoost, LightGBM, CatBoost) | High-dimensional feature sets including engagement history and content signals | Conversion probability, expected revenue, churn probability | RMSE / MAE | Sequential error correction; high accuracy on tabular data |
| Neural Networks | Subject-line embeddings, multi-channel behavior, long engagement histories | Open probability, conversion probability, expected revenue | AUC / F1 | Best for large datasets with unstructured inputs; less interpretable |
For continuous targets like expected open rate or expected revenue, researchers usually use RMSE and MAE to track forecast error. One open-rate prediction study using subject-line and sender features reported an R² of 77.53%, RMSE of about 5.16, and MAE of about 3.60. That means the model explained most of the variation in open rates across campaigns.[2]
For binary targets like churn or conversion probability, F1-score and AUC are the standard benchmarks. F1 is especially useful when the positive outcome is rare, which is often the case in conversion or churn prediction.[16][17]
What Studies Show About Forecast Outcomes
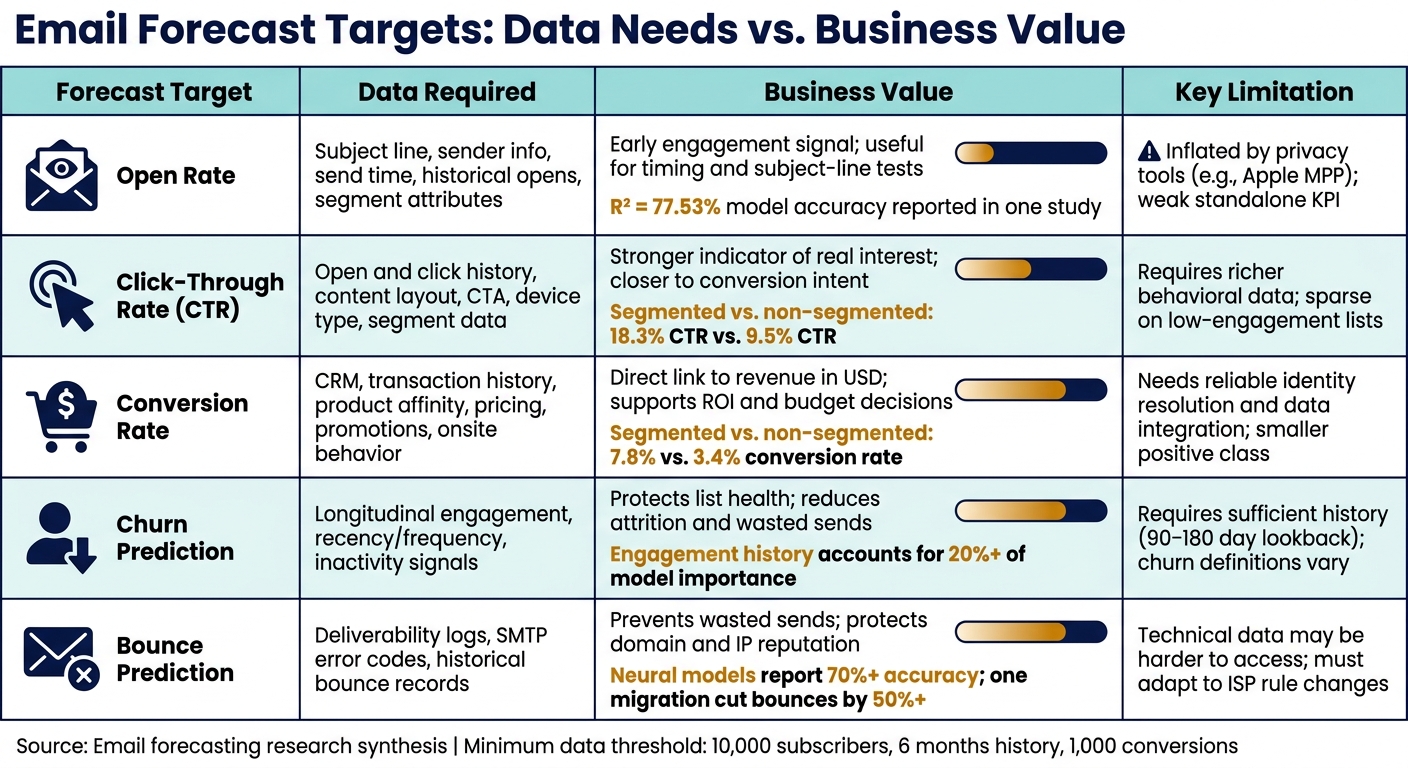
Email Forecast Targets: Data Needs vs. Business Value
The next step is figuring out which forecast target gives you the strongest acquisition signal.
Open Rate Forecasting as the Most Common Benchmark
Open rate is still the benchmark most teams start with. It’s easy to track, easy to compare, and easy to model.
But there’s a catch: privacy updates have made open rate a shaky standalone KPI. Major email providers, including Apple Mail Privacy Protection, can auto-load tracking pixels even when no person actually opens the message. That can inflate open counts.[1][23][6] On top of that, open rate benchmarks swing a lot depending on the source and how the data was collected. So while opens are useful, they’re not a dependable way to judge forecast accuracy on their own.
Put simply, opens can help you benchmark performance. They’re just not the best stand-in for revenue.
Click-Through, Conversion, Churn, and Bounce Prediction
If you want a better read on what’s working, downstream metrics tell the clearer story. Models tied to segmentation and CRM data improve open and click prediction and help teams spot the subscribers most likely to convert.[1][6] Once email data is connected to CRM and e-commerce systems, those models can also score each subscriber for purchase propensity and lifetime value (LTV), which improves revenue forecasting in USD.[6]
One study showed just how large the gap can be. Behaviorally segmented campaigns produced a 42.5% open rate vs. 28.7%, an 18.3% CTR vs. 9.5%, and a 7.8% conversion rate vs. 3.4% compared to non-segmented sends.[25]
Churn and bounce prediction often have the most direct payoff because they cut waste before it happens. Churn models usually look at engagement over time, recency and frequency, and inactivity signals. Bounce prediction leans on deliverability logs and SMTP error codes. Neural models trained on SMTP logs and deliverability data have reported more than 70% accuracy in forecasting bounces, which helps teams clean lists before they send.[22] Rightmove’s deliverability migration led to a 10% uplift in CTR and more than 50% lower bounce rates.[24] Those gains matter because they protect sender reputation and help future campaigns keep landing in the inbox.
Forecast Targets Compared by Business Value
Higher-value targets need richer data. But they also do a better job of supporting acquisition planning.
| Forecast Target | Data Needed | Business Value | Common Limitations |
|---|---|---|---|
| Open rate | Subject line, sender info, send time, historical opens, segment attributes | Early engagement signal; useful for timing and subject-line tests | Inflated by privacy tools; weak as a sole KPI |
| Click-through rate | Open and click history, content layout, CTA, device type, segment data | Stronger indicator of real interest; closer to conversion intent | Requires richer behavioral data; sparse on low-engagement lists |
| Conversion rate | CRM, transaction history, product affinity, pricing, promotions, onsite behavior | Direct link to revenue in USD; supports ROI and budget decisions | Needs reliable identity resolution and data integration; smaller positive class |
| Churn prediction | Longitudinal engagement, recency/frequency, inactivity signals | Protects list health; reduces attrition and wasted sends | Requires sufficient history; churn definitions vary by business |
| Bounce prediction | Deliverability logs, SMTP error codes, historical bounce records | Prevents wasted sends; protects domain and IP reputation | Technical data may be harder to access; must adapt to ISP rule changes |
The research points in a pretty clear direction. Open rate is the easiest place to begin, but it has the weakest tie to revenue. Click, conversion, churn, and bounce forecasts take more work to build, yet they offer a much stronger link to business results, especially when acquisition budgets are tracked in dollars per new subscriber.[1][22][23][6]
Data Quality Limits and Key Takeaways
Clean Data, Minimum History, and Privacy Constraints
Even the best forecasting model falls apart when the input data is messy. Incomplete engagement records, uneven campaign tagging, and missing CRM or transaction data are some of the main reasons forecasts miss the mark.
Data volume matters too. A practical benchmark is at least 10,000 subscribers with engagement history, at least 6 months of campaign history, and at least 1,000 conversion events before you lean too hard on predictive models.[3] If you’re below those numbers, forecasts tend to get shaky.
Privacy changes make things tougher. As tracking gets blocked or delayed – especially open-based signals – forecasts have to lean more on downstream actions like clicks, site visits, purchases, and CRM events.[27][28] The smart move is to treat tracking behavior as something that can shift. Build that uncertainty into your analysis, and keep checking data quality over time, not just once at setup.
Where Small Businesses Should Start
For small businesses, the first job is simple: set up one reporting view that ties sends to revenue. After that, standardize campaign naming and UTM tagging so you can compare results across sends, segments, and offers.[26]
Once that foundation is in place, keep an eye on a small set of core variables:
- Send time
- Subject line
- Audience segment
- Device type
- Outcome metrics like open rate, CTR, conversion rate, unsubscribe rate, and bounce rate
Forecasts also work better when you segment by behavior instead of treating the full list like one big audience. New leads, repeat buyers, and dormant contacts don’t act the same way, and one average rate won’t tell the full story.
Then comes the part many teams skip: compare predicted results with actual results after each send. If the same gaps keep showing up, adjust your assumptions.[29][30] A forecast only helps if it lines up with what each segment is doing.
Conclusion: Key Findings on How Data Improves Email Forecasting
The research points to a plain rule: better data leads to better forecasts. That becomes even more true when email, CRM, and transaction records are tied together. On the flip side, weak data hygiene limits reliability no matter how advanced the model looks.
Validation against actual send results helps forecasts improve over time. For most teams, the biggest wins come from cleaner inputs and tighter tracking discipline – not from chasing more advanced algorithms.
FAQs
What data matters most for accurate email forecasting?
Prioritize high-quality, consolidated data across the full customer journey, not just isolated campaign metrics. The core inputs are impressions, clicks, conversions, and costs, tracked through CRM integrations and UTM parameters so you can tie revenue back to each channel.
You should also use at least six months of historical data to account for seasonality and shifts in buyer behavior. For email, pay close attention to open rates, click-through rates, conversion rates, and revenue per email, then check those numbers against your CRM to make sure they line up.
How much historical data do I need before forecasting?
In most cases, 6 to 12 months of historical data is enough to set a baseline and spot seasonal patterns.
If you’re working on more advanced forecasting, like ROI tracking or long-term LTV predictions, it’s better to use 18 to 24 months of data.
You can make simple methods work with less. But the data needs to be consistent and clean. One messy spreadsheet can throw the whole thing off.
It also helps to look at major business changes along the way. A product launch, pricing update, or shift in strategy can make older data less useful for what you’re trying to predict now.
Which email metrics are better to forecast than opens?
For more accurate email acquisition forecasting, focus on metrics tied to actual engagement and business impact. Open rates are less dependable now because of privacy protections and technical limits.
A better set of metrics includes:
- CTR and CTOR to measure clicks and interaction
- Conversion rate for sign-ups or purchases
- Revenue per email to track financial impact
- Reading time to gauge attention