

Multi-cloud AI usually breaks in the same five places: platform mismatch, weak data rules, cross-cloud delays and fees, security gaps, and split model workflows. If you want AI to work across AWS, Azure, and Google Cloud, I’d focus on five fixes first: standard formats, shared data rules, less data movement, one security model, and one release and monitoring process.
Here’s the short version:
- Interoperability issues happen when APIs, schemas, model packages, and identity systems don’t match.
- Governance and lineage gaps lead to bad definitions, weak audit trails, and AI outputs people stop trusting.
- Latency and egress costs grow when teams keep moving data between clouds instead of processing it where it sits.
- Security and compliance risks increase with each extra cloud, region, service, and policy difference.
- MLOps fragmentation causes version drift, manual handoffs, slower releases, and more production failures.
A few numbers make the problem clear:
- 89% of organizations use multi-cloud.
- Cross-cloud data integration issues rose from 37% to 45% year over year.
- Cross-cloud calls can add 10–100+ ms of delay.
- One multi-cloud design cut egress by 45% and saved about $1,200/month.
- Teams without release automation see a 71% higher production failure rate.
5 Multi-Cloud AI Integration Challenges: Causes, Costs & Fixes
AWS re:Invent 2025 – Architecting multicloud solutions from data mesh to generative AI (HMC210)
sbb-itb-2ec70df
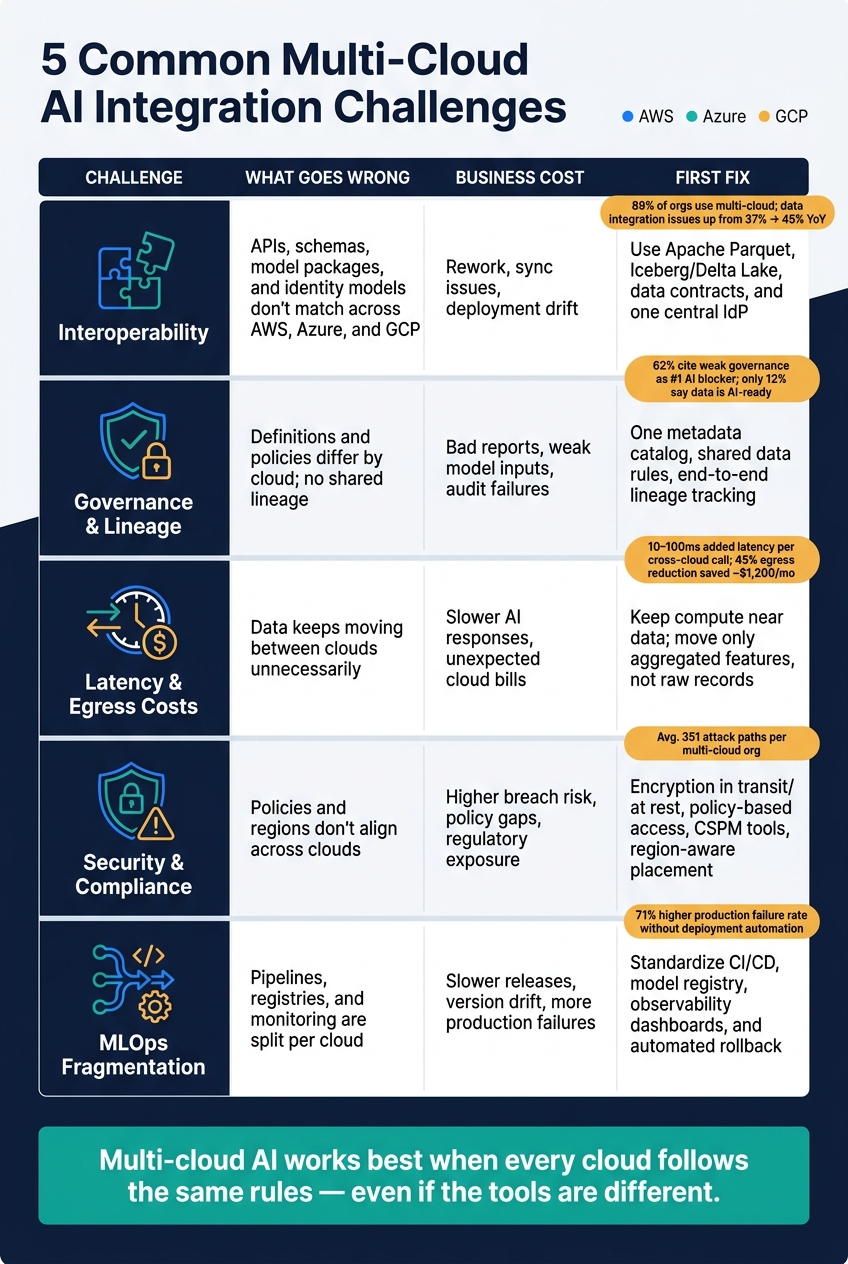
Quick Comparison
| Challenge | What goes wrong | Business cost | What I’d do first |
|---|---|---|---|
| Interoperability | Clouds use different APIs, formats, and identity models | More rework, sync issues, deployment drift | Use Parquet, Iceberg or Delta, data contracts, and one IdP |
| Governance and lineage | Definitions and policies differ by cloud | Bad reports, weak model inputs, audit trouble | Set one metadata catalog, shared rules, and end-to-end lineage |
| Latency and transfer costs | Data keeps moving between clouds | Slower apps and higher monthly cloud bills | Keep compute near data and move only what you need |
| Security and compliance | Policies and regions don’t line up | More exposure, policy gaps, legal risk | Use encryption, policy-based access, CSPM, and region-aware placement |
| MLOps coordination | Pipelines and monitoring are split | Slower releases and more production issues | Standardize CI/CD, model registry, alerts, and rollback |
If I had to sum it up in one line, it would be this: multi-cloud AI works best when every cloud follows the same rules, even if the tools are different.
Interoperability across cloud platforms
When AI workloads span AWS, Azure, and Google Cloud, teams run into a simple problem fast: each platform has its own APIs, storage formats, and identity model. That means more integration work, more edge cases, and more things to keep in sync. And this isn’t a niche issue. Flexera‘s 2024 State of the Cloud report found that 89% of organizations use multi-cloud, and the share dealing with data integration between clouds climbed from 37% to 45% year over year.[1] In practice, the first crack usually appears where data, models, and identity meet.
Where integration breaks first
The first friction tends to show up at the handoff points, where one system needs to pass information to another and the two don’t line up cleanly.
Data schemas are a common source of trouble. A U.S. retailer might define customer_id one way in one cloud and track order_date a bit differently in another. Those small mismatches can stall model training and throw off downstream reporting.
Model packaging creates another problem. Different clouds often expect different packaging formats, so teams end up maintaining duplicate deployment paths. And here’s the tricky part: a model can run fine in one environment, then behave a little differently in another because of small runtime differences, with no clear failure message to flag it.
Identity is another sticking point. Each major cloud uses its own identity model and token format, so teams have to map one system to another.[2][3] Without one shared identity approach, access grants turn into one-off decisions, audits become manual work, and misconfiguration risk grows every time a new service gets added.
How standardized interfaces reduce platform friction
The way out is standardization, not piling on more custom adapters. Teams need to agree early on formats, contracts, and access patterns, ideally before a second or third cloud joins the stack.
A good place to start is analytical data storage. Open, portable formats like Apache Parquet, along with open table formats such as Apache Iceberg or Delta Lake, make it much easier to work across providers.[6][7] Multiple query engines in different clouds can read these formats, which helps keep business logic from getting tied to a single vendor. Apache Iceberg often comes up as a strong option for multi-cloud lakehouses when portability matters most.[8][9]
Shared data contracts push this further. A data contract sets the rules for field names, data types, allowed values, and units across core domains like customers, orders, and events. Then every pipeline has to follow those same rules, no matter which cloud it runs on. That cuts down schema drift and saves teams from doing a brand-new mapping exercise every time a use case crosses a cloud boundary.
On the identity side, a central identity provider (IdP) with SSO and role mapping across clouds gives data scientists and ML engineers one login across environments. It also helps to define roles by business function, such as "ML Engineer – Credit Risk" or "Data Analyst – Marketing", then map those roles to matching permissions in each cloud. That replaces the patchwork of ad hoc access rules that tends to build up over time.[3][4]
Federated query patterns help too. They let teams query data across clouds without moving it around first, which can cut egress fees and reduce pipeline duplication. A federated catalog gives analysts and engineers one place to search for datasets, review data quality, and trace lineage, even when the assets sit in different providers.[5]
Once interoperability is handled, the next pressure point is governance and lineage that work the same way across clouds.
Data governance and lineage gaps
Even when platforms connect, AI still falls apart if data definitions, ownership, and lineage don’t match across clouds.
This usually starts with a simple mess: the same data lives in different clouds, but each one follows different rules. 62% of organizations say weak data governance is the main issue slowing down AI work.[10][11][13] And only 12% say their data is good enough and easy enough to access for AI to work well.[10][12]
Once catalogs are disconnected, one field can mean one thing in Cloud A and something else in Cloud B. That slow drift poisons customer segmentation models, attribution reports, and lead scoring.
You can see the damage pretty fast. Sales teams stop trusting AI lead scores because the "best" leads don’t convert. Marketing dashboards show ROAS numbers that don’t match finance exports. Leaders ask for the real number and get a different answer depending on the tool.
Missing lineage makes all of this worse. If no one can trace how data moved, changed, or got joined along the way, attribution models can shift for no clear reason. Teams can’t explain AI recommendations to stakeholders or auditors. Trust starts to crack. Add in time-zone issues, duplicate profiles, and currency-format mismatches, and now models, audience counts, and ad spend data all get skewed.
The answer is a shared governance layer that keeps definitions, access, and lineage lined up across clouds.
A centralized metadata catalog helps lock in one definition for each key metric and entity across environments, like customer, lead, campaign, and order. Then you pair that with end-to-end lineage tracking, from ingestion to model output and dashboard reporting. If a number suddenly changes or something breaks, lineage gives teams a way to trace the source instead of guessing.
Policy-driven governance also puts access, masking, and data quality rules straight into pipelines. With shared access control across clouds, teams are less likely to run into that awkward situation where one group can see raw user-level data in one system while another group only sees rolled-up data somewhere else.
And the payoff isn’t small. Organizations with structured governance programs report 58% improved data quality and 58% improved quality of analytics and insights.[10][13]
With governance in place, the next constraint is how much time, cost, and risk data movement adds.
Latency, transfer costs, and security risks
After governance, the next limit is simple: where data moves, and where it should not move. Even if governance is set up, pushing data across clouds can slow pipelines, drive up spend, and add security trouble.
How data movement hurts speed and budget
Cross-cloud API calls can add 10–100+ milliseconds of latency compared with local calls.[21] That delay can slow training and make real-time inference less responsive.
Then there’s the money side. Cloud providers often charge when data leaves their platform. So each transfer from one cloud to another can trigger egress fees. If teams keep copying the same data for backups, model retraining, testing, and analytics syncs, the bill can climb fast.
One proof-of-concept in a multi-cloud data architecture showed this clearly: grouping ingestion and transformation tasks by cloud provider before exchanging data cut cross-cloud egress by 45%, which saved about $1,200/month in a scaled environment.[15] The answer wasn’t a new tool. It was smarter workload placement.
The fixes tend to be pretty straightforward:
- Data locality: process data where it already lives
- Selective movement: send aggregated features instead of raw records
- Workload placement by use case: keep latency-sensitive inference close to the data source, and keep large-scale training near the main data repository
For high-volume, steady flows, private connectivity links like AWS Direct Connect, Azure ExpressRoute, or Google Cloud Interconnect can cut per-GB egress rates. That said, fixed circuit fees still need to be weighed against the savings.[14][16]
How to reduce privacy and compliance exposure
Each extra cloud gives attackers more room to work and gives teams more chances to drift into bad configs. Cloud security research found that more than half of organizations have at least one attack path across their multi-cloud environment, with an average of 351 attack paths per organization.[19]
For U.S. businesses handling customer data, the baseline should include encryption in transit and at rest, policy-based access control, and continuous compliance monitoring across every cloud. That helps keep model inputs, outputs, and audit trails trustworthy.
Region-aware data placement matters too. Sensitive data – especially personally identifiable information or detailed behavioral analytics – should stay in approved regions or systems when legal, contract, or customer commitments say it must. In practice, that often means keeping raw PII in one controlled environment and sending only masked or tokenized records to other clouds.
Tools like CSPM (Cloud Security Posture Management) platforms and automated policy enforcement can help apply these rules across AWS, Azure, and GCP without leaning on manual checks.[17][18][20]
Challenge vs. business impact vs. solution: comparison table
| Challenge | Business Impact | Solution |
|---|---|---|
| Cross-cloud latency | Slower AI responses and reduced value of dashboards and AI copilots | Data locality, workload placement by use case |
| Egress fees and repeated replication | Unexpected cloud bills from frequent cross-cloud transfers | Move only changes, use private connectivity |
| Expanded attack surface | Higher breach risk and misconfiguration spread across clouds | Encryption in transit and at rest, policy-based access controls |
| Inconsistent compliance posture | Audit failures, policy violations, regulatory exposure | Continuous compliance monitoring, CSPM tools, automated policy enforcement |
| Sovereignty and data residency gaps | Legal and contractual risk for regulated customer data | Region-aware data placement, tokenization before cross-cloud transfer |
Even if data movement is handled well, AI delivery can still stall when MLOps workflows stay fragmented.
Operational complexity and MLOps coordination
Once data movement is under control, the next place things often go wrong is model operations. Pipelines may look stable on paper, but AI delivery can still fall apart when teams manage models across multiple cloud platforms without a shared way of working.
One common problem is version skew. When build, test, and deployment pipelines run separately in each cloud, one environment can drift away from the others. A model might be updated in AWS but stay old in Azure or GCP. Teams may not spot the mismatch until something breaks in production.
Monitoring has the same issue. CloudWatch, Azure Monitor, and Stackdriver all report metrics in their own way. That forces engineers to compare logs by hand across platforms just to figure out why a model is underperforming. The result is slower response times and a higher chance that users notice the problem before the team does.
The cost to the business shows up fast: slower releases and less value from AI. Companies without deployment automation see a 71% higher production failure rate than teams using automated release processes.[22][23]
Manual handoffs make the mess worse. Model transfers often happen through tickets, email threads, or shared folders. That’s where misconfigured endpoints, missing environment variables, and slow approvals creep in. And when a release needs to go live before a holiday campaign or a quarterly sales push, those delays hurt.
The fix starts with four layers that should work the same way across clouds:
- Source control
- CI/CD
- Model registry
- Deployment orchestration
A central Git repository, clear branching rules, reusable pipeline templates that hide cloud-specific steps, and a shared model registry help keep versions and performance in sync.
Shared observability is what ties the whole system together. A single observability layer that pulls in logs, metrics, and distributed traces from AWS, Azure, and GCP into one set of dashboards gives teams an end-to-end view of model health. No more piecing together reports from three consoles and hoping the story lines up.
Standardized alerts linked to business-facing SLOs help too. For example, if a customer-facing API crosses a prediction latency threshold, teams can describe the issue in terms leadership cares about, not just raw system metrics. Automated retraining based on data drift or performance thresholds helps keep models current without constant manual work. And automated rollback policies matter just as much: if a deployment fails in one cloud, the system can revert on its own instead of waiting for someone to notice.
For smaller organizations in the U.S., open-source tools for experiment tracking, orchestration, and infrastructure consistency can cover a lot of this ground without enterprise-level spending.
A simple RACI chart also helps more than many teams expect. When responsibility is clearly assigned across development, validation, deployment, monitoring, and retirement, ownership gaps shrink. That cuts down on slow incident response and lowers audit risk.
That leads straight to the next operational issue: how to make multi-cloud AI repeatable.
Conclusion: The core fixes that make multi-cloud AI work
The thread running through all of this is operational consistency: one way to govern data, deploy models, and track performance across clouds.
Multi-cloud AI tends to break down when each cloud follows different rules for data, models, access, and day-to-day operations. That creates drag fast. Architecture, governance, and operations need to work the same way no matter where a workload runs. All five issues trace back to the same problem: inconsistency across clouds.
The fix is also the same each time: reduce inconsistency with standardized interfaces, unified lineage, compute-near-data design, cross-cloud identity controls, and one monitoring layer that covers every environment.
Key takeaways for business leaders
The first shift is simple: start with friction, not features. Look at your highest-value AI use cases and map them to their data sources. Then score each integration flow by how often it fails and what that failure costs the business. Fix the small set of high-friction patterns that create the most delay or risk before you expand.
A few priorities stand out:
- Place workloads where data location, latency, compliance, and total cost make the most sense.
- Set governance rules before you scale. Define data ownership, access policies, and lineage rules early so you don’t end up patching them in after AI systems are already live.
- Standardize monitoring before scaling workloads.
- Tie each AI initiative to one measurable business metric.
For leaders, the test is straightforward: if a cloud adds friction, cost, or risk, standardize it before scaling the next AI use case.
FAQs
Which multi-cloud AI issue should you fix first?
Start by putting a strong governance framework in place, along with centralized security policies. Standardize IAM, encryption, and compliance monitoring across every provider so your team can cut complexity and avoid security gaps.
It also helps to adopt a zero-trust model early. That gives you a cleaner way to protect sensitive data, simplify day-to-day operations, and build a scalable base for handling latency and data integration with more consistency.
How can we reduce cross-cloud data transfer costs?
Process data close to the point of ingestion instead of shuffling it back and forth. That simple shift can cut a lot of waste. Rather than copying entire datasets, replicate only aggregated results, and use CDC to pick up changes without relying on full bulk loads.
It also helps to standardize on formats like Parquet, Avro, or JSON. For datasets larger than 100 GB, use intermediate cloud storage as a handoff layer. And if you need to work across more than one cloud, apply data federation so teams can query data across platforms without moving it first.
Why does this matter so much? Because egress fees can eat up 10–20% of total cloud spend. If data keeps bouncing around, those charges add up fast.
What tools help standardize MLOps across clouds?
Standardizing MLOps across multi-cloud setups usually comes down to a mix of orchestration, monitoring, and infrastructure tools.
- Apache Airflow, Dagster, and Orchestra help manage workflows across clouds.
- OpenTelemetry supports unified telemetry collection and is often paired with Grafana or Prometheus for visibility.
- Terraform helps standardize infrastructure and data quality rules as code, which makes deployments more consistent and easier to track in version control.